Technology Advice for Small Businesses

powered by Pronto Marketing

Windows Update failures explained: Why they happen and how to fix them
A Windows Update failure is frustrating partly because the error messages rarely explain what actually went wrong. The update either hangs, rolls back, or throws an error code, and the system offers nothing useful about the cause. Understanding the underlying causes behind most Windows Update problems makes troubleshooting considerably more logical. Each points to a distinct set of fixes, applied in order from simplest to most involved.

1. Transient issues that a restart resolves

A significant number of Windows Update failures are caused by temporary system states: a previous update that downloaded but hasn’t been applied yet, a service that needs to restart to release a file lock, or a pending operation that is blocking the installation from proceeding. Windows needs a full restart to clear these states, and attempting another update without restarting first often produces the same failure.

After restarting, go to Settings > Windows Update and click Check for updates to trigger a fresh attempt. If the connection is working and no other issues are present, this step frequently solves the issue.

Network issues operate the same way. Because Windows Update relies on a steady stream from Microsoft’s servers, subtle drops or proxy restrictions can stall a download without raising an obvious error. If a fresh reboot doesn’t work, test your internet stability or temporarily toggle off any active VPNs before moving to file system diagnostics.

2. Insufficient disk space

Feature updates, in particular, require significant temporary storage during download and installation, often 10 to 15 GB for a major Windows 11 update. If the system drive is nearly full, the update will fail at the download or installation stage, frequently producing error code 0x80070070 or similar. The fix is freeing up space before reattempting.

Disk Cleanup (accessible through the Start menu or by right-clicking the drive in File Explorer and selecting Properties) can recover space from temporary files, the Windows update cache, and delivery optimization files. Uninstalling unused applications and clearing the Downloads folder are two more easy ways to free up space. Feature updates also require that the system is not currently running the Windows installation on a drive that is nearly full, so this is worth checking before troubleshooting anything more complex.

3. Corrupted update components

Windows stores downloaded update packages in the SoftwareDistribution folder and stores update package signatures in the catroot2 folder. If either of these becomes corrupted, subsequent update attempts will fail even when the connection is working and disk space is adequate. Corrupted system files can produce the same result.

Windows provides two tools for addressing this. System File Checker (SFC) scans for corrupted system files and repairs them using a cached copy. It runs from an elevated Command Prompt with the command sfc /scannow. The Deployment Image Servicing and Management tool (DISM) repairs the Windows system image itself, pulling replacement files from Windows Update when needed. Run it in the same elevated Command Prompt with DISM.exe /Online /Cleanup-Image /RestoreHealth after SFC completes. Restart after both tools finish, then retry the update.

For cases where the SoftwareDistribution folder itself is the problem, Windows Update services can be stopped temporarily, the folder renamed to force Windows to rebuild it fresh, and the services restarted. This is an advanced step; following Microsoft’s documented procedure or a verified IT reference for the exact command sequence is recommended.

4. Specific updates that consistently fail

Sometimes, a specific update repeatedly fails through standard channels even on an otherwise healthy PC. While this happens more frequently with optional updates and hardware drivers than critical security patches, it can affect any package. When it does, you can bypass the glitchy update pipeline entirely by going directly to the Microsoft Update Catalog (catalog.update.microsoft.com). Just search for the update’s KB number — found in your Windows Update history or error message — download the matching package for your system architecture, and run the installer.

Manual installation sidesteps the broken step in the background update process, applying the patch cleanly and updating your system’s error log in the process.

When the problem is deeper

If these steps don’t solve the problem, you’re likely facing a deeper issue within Windows itself. An in-place upgrade reinstalls Windows while keeping all your files, apps, and settings intact, making it a great way to fix deep-seated update bugs without starting over. A clean install is the absolute last resort and requires backing up your data first. Keep in mind that heavy fixes like these are rarely necessary; the steps above clear up almost all Windows Update issues.

If your business is dealing with persistent Windows Update problems across multiple devices, our team can diagnose and resolve update failures at scale and keep your systems current and protected. Get in touch.
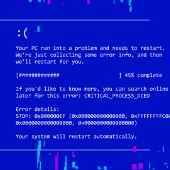
A practical guide to diagnosing and resolving Windows Update issues

The error messages Windows Update displays during a failed update are rarely self-explanatory. What they describe is a symptom, not a cause. Most update failures, though, trace back to one of four root causes, and each has a clear resolution path. Working through them in order from least disruptive to most involved resolves the vast majority of cases.
1. Transient issues that a restart resolves

A significant number of Windows Update failures are caused by temporary system states: a previous update that downloaded but hasn’t been applied yet, a service that needs to restart to release a file lock, or a pending operation that is blocking the installation from proceeding. Windows needs a full restart to clear these states, and attempting another update without restarting first often produces the same failure.

After restarting, go to Settings > Windows Update and click Check for updates to trigger a fresh attempt. If the connection is working and no other issues are present, this step frequently solves the issue.

Network issues operate the same way. Because Windows Update relies on a steady stream from Microsoft’s servers, subtle drops or proxy restrictions can stall a download without raising an obvious error. If a fresh reboot doesn’t work, test your internet stability or temporarily toggle off any active VPNs before moving to file system diagnostics.

2. Insufficient disk space

Feature updates, in particular, require significant temporary storage during download and installation, often 10 to 15 GB for a major Windows 11 update. If the system drive is nearly full, the update will fail at the download or installation stage, frequently producing error code 0x80070070 or similar. The fix is freeing up space before reattempting.

Disk Cleanup (accessible through the Start menu or by right-clicking the drive in File Explorer and selecting Properties) can recover space from temporary files, the Windows update cache, and delivery optimization files. Uninstalling unused applications and clearing the Downloads folder are two more easy ways to free up space. Feature updates also require that the system is not currently running the Windows installation on a drive that is nearly full, so this is worth checking before troubleshooting anything more complex.

3. Corrupted update components

Windows stores downloaded update packages in the SoftwareDistribution folder and stores update package signatures in the catroot2 folder. If either of these becomes corrupted, subsequent update attempts will fail even when the connection is working and disk space is adequate. Corrupted system files can produce the same result.

Windows provides two tools for addressing this. System File Checker (SFC) scans for corrupted system files and repairs them using a cached copy. It runs from an elevated Command Prompt with the command sfc /scannow. The Deployment Image Servicing and Management tool (DISM) repairs the Windows system image itself, pulling replacement files from Windows Update when needed. Run it in the same elevated Command Prompt with DISM.exe /Online /Cleanup-Image /RestoreHealth after SFC completes. Restart after both tools finish, then retry the update.

For cases where the SoftwareDistribution folder itself is the problem, Windows Update services can be stopped temporarily, the folder renamed to force Windows to rebuild it fresh, and the services restarted. This is an advanced step; following Microsoft’s documented procedure or a verified IT reference for the exact command sequence is recommended.

4. Specific updates that consistently fail

Sometimes, a specific update repeatedly fails through standard channels even on an otherwise healthy PC. While this happens more frequently with optional updates and hardware drivers than critical security patches, it can affect any package. When it does, you can bypass the glitchy update pipeline entirely by going directly to the Microsoft Update Catalog (catalog.update.microsoft.com). Just search for the update’s KB number — found in your Windows Update history or error message — download the matching package for your system architecture, and run the installer.

Manual installation sidesteps the broken step in the background update process, applying the patch cleanly and updating your system’s error log in the process.

When the problem is deeper

If these steps don’t solve the problem, you’re likely facing a deeper issue within Windows itself. An in-place upgrade reinstalls Windows while keeping all your files, apps, and settings intact, making it a great way to fix deep-seated update bugs without starting over. A clean install is the absolute last resort and requires backing up your data first. Keep in mind that heavy fixes like these are rarely necessary; the steps above clear up almost all Windows Update issues.

If your business is dealing with persistent Windows Update problems across multiple devices, our team can diagnose and resolve update failures at scale and keep your systems current and protected. Get in touch.

Why Windows Update fails and how to fix it

Most Windows Update failures stem from four main issues: transient glitches, corrupt system files, insufficient storage, or network connectivity. Spotting the root cause early lets you jump straight to the right solution instead of wasting time working down a generic troubleshooting guide.
1. Transient issues that a restart resolves

A significant number of Windows Update failures are caused by temporary system states: a previous update that downloaded but hasn’t been applied yet, a service that needs to restart to release a file lock, or a pending operation that is blocking the installation from proceeding. Windows needs a full restart to clear these states, and attempting another update without restarting first often produces the same failure.

After restarting, go to Settings > Windows Update and click Check for updates to trigger a fresh attempt. If the connection is working and no other issues are present, this step frequently solves the issue.

Network issues operate the same way. Because Windows Update relies on a steady stream from Microsoft’s servers, subtle drops or proxy restrictions can stall a download without raising an obvious error. If a fresh reboot doesn’t work, test your internet stability or temporarily toggle off any active VPNs before moving to file system diagnostics.

2. Insufficient disk space

Feature updates, in particular, require significant temporary storage during download and installation, often 10 to 15 GB for a major Windows 11 update. If the system drive is nearly full, the update will fail at the download or installation stage, frequently producing error code 0x80070070 or similar. The fix is freeing up space before reattempting.

Disk Cleanup (accessible through the Start menu or by right-clicking the drive in File Explorer and selecting Properties) can recover space from temporary files, the Windows update cache, and delivery optimization files. Uninstalling unused applications and clearing the Downloads folder are two more easy ways to free up space. Feature updates also require that the system is not currently running the Windows installation on a drive that is nearly full, so this is worth checking before troubleshooting anything more complex.

3. Corrupted update components

Windows stores downloaded update packages in the SoftwareDistribution folder and stores update package signatures in the catroot2 folder. If either of these becomes corrupted, subsequent update attempts will fail even when the connection is working and disk space is adequate. Corrupted system files can produce the same result.

Windows provides two tools for addressing this. System File Checker (SFC) scans for corrupted system files and repairs them using a cached copy. It runs from an elevated Command Prompt with the command sfc /scannow. The Deployment Image Servicing and Management tool (DISM) repairs the Windows system image itself, pulling replacement files from Windows Update when needed. Run it in the same elevated Command Prompt with DISM.exe /Online /Cleanup-Image /RestoreHealth after SFC completes. Restart after both tools finish, then retry the update.

For cases where the SoftwareDistribution folder itself is the problem, Windows Update services can be stopped temporarily, the folder renamed to force Windows to rebuild it fresh, and the services restarted. This is an advanced step; following Microsoft’s documented procedure or a verified IT reference for the exact command sequence is recommended.

4. Specific updates that consistently fail

Sometimes, a specific update repeatedly fails through standard channels even on an otherwise healthy PC. While this happens more frequently with optional updates and hardware drivers than critical security patches, it can affect any package. When it does, you can bypass the glitchy update pipeline entirely by going directly to the Microsoft Update Catalog (catalog.update.microsoft.com). Just search for the update’s KB number — found in your Windows Update history or error message — download the matching package for your system architecture, and run the installer.

Manual installation sidesteps the broken step in the background update process, applying the patch cleanly and updating your system’s error log in the process.

When the problem is deeper

If these steps don’t solve the problem, you’re likely facing a deeper issue within Windows itself. An in-place upgrade reinstalls Windows while keeping all your files, apps, and settings intact, making it a great way to fix deep-seated update bugs without starting over. A clean install is the absolute last resort and requires backing up your data first. Keep in mind that heavy fixes like these are rarely necessary; the steps above clear up almost all Windows Update issues.

If your business is dealing with persistent Windows Update problems across multiple devices, our team can diagnose and resolve update failures at scale and keep your systems current and protected. Get in touch.

Planning a private cloud? 4 things to get right before you build anything

The appeal of a private cloud is straightforward: dedicated infrastructure, greater control over data, and the ability to customize the environment to your specific workloads. However, the execution is harder than it looks. Four common mistakes account for most private cloud deployments that fail to deliver on their initial promise.
Underestimating infrastructure requirements

Private clouds are hardware-heavy by design. To work properly, they need processors built for virtualization, redundant high-speed storage, fast networking, and enough overhead to handle real-world demands. When organizations try to cut corners using underpowered or aging equipment, the system usually collapses under its own weight right after launch.

Outdated hardware creates immediate bottlenecks, stretches out recovery times during outages, and frequently fails to support modern virtualization platforms. Rather than trying to force legacy equipment to do a job it wasn’t built for, the right approach is designing for your actual workload demands from day one.

If building out dedicated infrastructure upfront isn’t feasible, a hosted private cloud is often a smarter path. A third-party provider manages the underlying hardware while you retain full logical control and isolation, giving you the security and privacy benefits without the heavy capital expense.

Skipping automation and management tooling

If operating your private cloud takes constant manual effort, it isn’t really functioning as a cloud — it’s just a traditional server setup with extra steps. The whole point of cloud infrastructure is being able to scale and manage resources on demand without drowning your team in admin work. That agility relies completely on automation.

When teams manage a cloud using old-school IT habits, engineers waste hours on user provisioning, resource allocation, and basic setups that automated tools could handle in seconds. The result? A rigid system that’s slow to adapt, prone to human error, and expensive to run.

The key to avoiding this trap is picking your management tools during the initial design phase, not after launch. By choosing platforms that fit your existing setup and automate routine tasks from day one, you keep your cloud agile and avoid the headache of retrofitting live systems later.

Inadequate security and access planning

Too often, teams launch the cloud first and leave security configuration for later. This issue is especially critical in regulated environments where frameworks such as HIPAA and PCI DSS require strict data tracking and access governance. Without proper controls from the beginning, a private cloud risks noncompliance before processing its first workload.

The fix is defining role-based access controls, logging policies, and compliance baselines during the initial architecture phase. Building these safeguards into the foundation ensures your cloud remains secure and fully audit-ready from day one.

Treating maintenance as optional

A private cloud isn’t something you set up and forget. It demands steady, ongoing care; you need to update software, deploy security patches, manage capacity, and keep track of configuration changes. When teams manage a cloud reactively, the system slowly degrades. Unapplied patches leave security gaps, and unmanaged workload growth quietly erodes performance until the whole environment feels sluggish and unstable.

The solution is straightforward: assign explicit ownership for cloud maintenance. Whether that responsibility lands on an internal team member, a dedicated administrator, or a managed service provider, someone needs to own the maintenance schedule.

Having a clear owner ensures system health is monitored regularly and the infrastructure evolves alongside your business, rather than sitting unchanged until something breaks.

Thinking about building or redesigning your private cloud environment? Our team can help you assess your infrastructure requirements, design a scalable approach, and avoid the deployment mistakes that catch most organizations off guard. Get in touch to start the planning process.

The private cloud problems organizations don’t see coming, and how to avoid them

Private cloud deployments have a higher failure rate than their public cloud counterparts, largely because organizations underestimate what they require. The control and security benefits are real, but they come with infrastructure demands, management complexity, and ongoing maintenance requirements that public cloud providers absorb on your behalf. Understanding the four most common deployment mistakes is the most practical way to avoid them.
Underestimating infrastructure requirements

Private clouds are hardware-heavy by design. To work properly, they need processors built for virtualization, redundant high-speed storage, fast networking, and enough overhead to handle real-world demands. When organizations try to cut corners using underpowered or aging equipment, the system usually collapses under its own weight right after launch.

Outdated hardware creates immediate bottlenecks, stretches out recovery times during outages, and frequently fails to support modern virtualization platforms. Rather than trying to force legacy equipment to do a job it wasn’t built for, the right approach is designing for your actual workload demands from day one.

If building out dedicated infrastructure upfront isn’t feasible, a hosted private cloud is often a smarter path. A third-party provider manages the underlying hardware while you retain full logical control and isolation, giving you the security and privacy benefits without the heavy capital expense.

Skipping automation and management tooling

If operating your private cloud takes constant manual effort, it isn’t really functioning as a cloud — it’s just a traditional server setup with extra steps. The whole point of cloud infrastructure is being able to scale and manage resources on demand without drowning your team in admin work. That agility relies completely on automation.

When teams manage a cloud using old-school IT habits, engineers waste hours on user provisioning, resource allocation, and basic setups that automated tools could handle in seconds. The result? A rigid system that’s slow to adapt, prone to human error, and expensive to run.

The key to avoiding this trap is picking your management tools during the initial design phase, not after launch. By choosing platforms that fit your existing setup and automate routine tasks from day one, you keep your cloud agile and avoid the headache of retrofitting live systems later.

Inadequate security and access planning

Too often, teams launch the cloud first and leave security configuration for later. This issue is especially critical in regulated environments where frameworks such as HIPAA and PCI DSS require strict data tracking and access governance. Without proper controls from the beginning, a private cloud risks noncompliance before processing its first workload.

The fix is defining role-based access controls, logging policies, and compliance baselines during the initial architecture phase. Building these safeguards into the foundation ensures your cloud remains secure and fully audit-ready from day one.

Treating maintenance as optional

A private cloud isn’t something you set up and forget. It demands steady, ongoing care; you need to update software, deploy security patches, manage capacity, and keep track of configuration changes. When teams manage a cloud reactively, the system slowly degrades. Unapplied patches leave security gaps, and unmanaged workload growth quietly erodes performance until the whole environment feels sluggish and unstable.

The solution is straightforward: assign explicit ownership for cloud maintenance. Whether that responsibility lands on an internal team member, a dedicated administrator, or a managed service provider, someone needs to own the maintenance schedule.

Having a clear owner ensures system health is monitored regularly and the infrastructure evolves alongside your business, rather than sitting unchanged until something breaks.

Thinking about building or redesigning your private cloud environment? Our team can help you assess your infrastructure requirements, design a scalable approach, and avoid the deployment mistakes that catch most organizations off guard. Get in touch to start the planning process.

Building a private cloud: 4 mistakes that derail most deployments

A private cloud gives organizations more control over their infrastructure than a public cloud, without the constraints that come with renting capacity from a major provider. Getting there, though, requires more careful planning than many organizations realize. Four mistakes account for a disproportionate share of private cloud deployments that underdeliver, overspend, or create more complexity than they resolve.
Underestimating infrastructure requirements

Private clouds are hardware-heavy by design. To work properly, they need processors built for virtualization, redundant high-speed storage, fast networking, and enough overhead to handle real-world demands. When organizations try to cut corners using underpowered or aging equipment, the system usually collapses under its own weight right after launch.

Outdated hardware creates immediate bottlenecks, stretches out recovery times during outages, and frequently fails to support modern virtualization platforms. Rather than trying to force legacy equipment to do a job it wasn’t built for, the right approach is designing for your actual workload demands from day one.

If building out dedicated infrastructure upfront isn’t feasible, a hosted private cloud is often a smarter path. A third-party provider manages the underlying hardware while you retain full logical control and isolation, giving you the security and privacy benefits without the heavy capital expense.

Skipping automation and management tooling

If operating your private cloud takes constant manual effort, it isn’t really functioning as a cloud — it’s just a traditional server setup with extra steps. The whole point of cloud infrastructure is being able to scale and manage resources on demand without drowning your team in admin work. That agility relies completely on automation.

When teams manage a cloud using old-school IT habits, engineers waste hours on user provisioning, resource allocation, and basic setups that automated tools could handle in seconds. The result? A rigid system that’s slow to adapt, prone to human error, and expensive to run.

The key to avoiding this trap is picking your management tools during the initial design phase, not after launch. By choosing platforms that fit your existing setup and automate routine tasks from day one, you keep your cloud agile and avoid the headache of retrofitting live systems later.

Inadequate security and access planning

Too often, teams launch the cloud first and leave security configuration for later. This issue is especially critical in regulated environments where frameworks such as HIPAA and PCI DSS require strict data tracking and access governance. Without proper controls from the beginning, a private cloud risks noncompliance before processing its first workload.

The fix is defining role-based access controls, logging policies, and compliance baselines during the initial architecture phase. Building these safeguards into the foundation ensures your cloud remains secure and fully audit-ready from day one.

Treating maintenance as optional

A private cloud isn’t something you set up and forget. It demands steady, ongoing care; you need to update software, deploy security patches, manage capacity, and keep track of configuration changes. When teams manage a cloud reactively, the system slowly degrades. Unapplied patches leave security gaps, and unmanaged workload growth quietly erodes performance until the whole environment feels sluggish and unstable.

The solution is straightforward: assign explicit ownership for cloud maintenance. Whether that responsibility lands on an internal team member, a dedicated administrator, or a managed service provider, someone needs to own the maintenance schedule.

Having a clear owner ensures system health is monitored regularly and the infrastructure evolves alongside your business, rather than sitting unchanged until something breaks.

Thinking about building or redesigning your private cloud environment? Our team can help you assess your infrastructure requirements, design a scalable approach, and avoid the deployment mistakes that catch most organizations off guard. Get in touch to start the planning process.

Your EHR will go offline eventually — here’s how to make sure your team is ready

An EHR downtime is the kind of event that reveals, quickly and concretely, whether a team has practiced for it or only planned for it. While planning establishes procedures on paper, practice builds the competence needed to carry them out under pressure. This guide covers six clinical and operational priorities for EHR downtime drills and explains how to build an exercise around each one.
Why drills expose what plans miss

When the EHR is unavailable, clinicians face specific, concrete problems: How do you confirm a patient’s identity without a pull-up? Where are the paper order forms? Who decides when to escalate a medication question that normally gets answered by checking the chart? These are procedural muscle-memory questions, and they are only answered reliably by practice rather than by reading a checklist.

The Academic Medical Center Patient Safety Organization’s downtime task force guidelines specifically recommend running drills as part of a complete downtime preparedness program, alongside staff training and a communication triage procedure. The US Department of Health and Human Services’ Administration for Strategic Preparedness and Response (ASPR) also provides a collection of EHR downtime resources to help healthcare organizations prepare for outages and maintain patient safety.

Patient identification: The highest-risk workflow

Analysis of patient safety events during EHR downtime consistently highlights patient identification and clinical information communication as the two areas of greatest risk. When the EHR system is unavailable, clinicians cannot verify patient identity through the standard electronic process, and the manual alternatives need to be established and practiced before they are needed.

The drill should walk through how staff confirm patient identity using two manual identifiers, where paper wristbands are stored and how they are applied, and what process is used to flag patients whose records may have been updated during the outage and need to be reconciled once the system returns. This is one of the areas where badge buddy cards, which are laminated reference sheets that attach to staff ID badges, have been shown in published implementation studies to improve nurse readiness.

Medication safety during downtime

Medication errors are among the most documented harms associated with EHR downtime. When the system is offline, pharmacy, nursing, and prescribing teams may lose access to current medication lists, allergy records, and order histories simultaneously. The drill should therefore test how each group handles this gap.

Specific scenarios to rehearse include:

Verifying an existing medication order without EHR access
Managing a new prescription when clinical decision support is unavailable
Communicating a critical allergy flag from nursing to pharmacy by paper
Handling a controlled substance order when the usual electronic verification cannot be completed

The Institute for Safe Medication Practices recommends assigning a dedicated downtime response team, with designated leaders on call to oversee medication safety during extended outages.

Documentation and order management

All orders, assessments, and clinical notes generated during downtime need to be documented on paper, tracked, and then entered into the EHR system during the recovery phase. The drill should confirm that paper forms are stocked, accessible, and understood by staff in each unit; that there is a defined process for numbering and collecting downtime documents; and that staff know which actions require immediate documentation versus which can be logged during recovery.

A standardized naming convention for patients seen during downtime is important for laboratory and radiology workflows, in particular, where specimens and images may need to be matched to a patient record that was created or updated while the EHR was unavailable.

Internal communications and escalation

When the EHR is offline, the communication infrastructure that coordinates care across departments also degrades. Automated alerts, results notifications, and order confirmations stop flowing. The drill should establish and test an alternative communication protocol: who notifies each clinical area when downtime begins, what the expected update frequency is, and what channel (telephone tree, whiteboard, radio) carries clinical communications during the event.

Escalation criteria should also be established in advance, since not every situation that triggers an EHR alert during normal operations warrants the same response during downtime. The drill should clarify which conditions require immediate escalation to a physician or charge nurse, regardless of system availability.

Recovery and reconciliation

Returning to full EHR functionality is not a passive event. Paper records created during downtime need to be scanned and entered, orders verified and reconciled, and any discrepancies between downtime documentation and the pre-downtime record resolved. The drill should cover who is responsible for each component of this reconciliation, how long it is expected to take, and what the priority order is for entering data generated during the outage.

A safe return to normal operations depends on how well these steps are coordinated. Research examining a major EHR downtime event in Australia highlighted the importance of effective communication during the transition back to electronic records. This recovery phase, sometimes called the uptime procedure, requires as much planning and coordination as the downtime response itself.

Our team helps healthcare practices and facilities develop and update EHR downtime procedures and clinical IT continuity plans, including practical drill programs tailored to their needs. Get in touch to discuss how we can help your organization prepare for EHR outages.

EHR downtime planning: What a useful drill actually covers (and what most skip)

Most healthcare organizations have an EHR downtime policy. Fewer have a practiced downtime procedure that clinical staff can execute under pressure. The two are different, and the gap between them is where patient safety risk lives. This article focuses on building a drill that trains the actual workflows your team will need when the system goes offline.
Why drills expose what plans miss

When the EHR is unavailable, clinicians face specific, concrete problems: How do you confirm a patient’s identity without a pull-up? Where are the paper order forms? Who decides when to escalate a medication question that normally gets answered by checking the chart? These are procedural muscle-memory questions, and they are only answered reliably by practice rather than by reading a checklist.

The Academic Medical Center Patient Safety Organization’s downtime task force guidelines specifically recommend running drills as part of a complete downtime preparedness program, alongside staff training and a communication triage procedure. The US Department of Health and Human Services’ Administration for Strategic Preparedness and Response (ASPR) also provides a collection of EHR downtime resources to help healthcare organizations prepare for outages and maintain patient safety.

Patient identification: The highest-risk workflow

Analysis of patient safety events during EHR downtime consistently highlights patient identification and clinical information communication as the two areas of greatest risk. When the EHR system is unavailable, clinicians cannot verify patient identity through the standard electronic process, and the manual alternatives need to be established and practiced before they are needed.

The drill should walk through how staff confirm patient identity using two manual identifiers, where paper wristbands are stored and how they are applied, and what process is used to flag patients whose records may have been updated during the outage and need to be reconciled once the system returns. This is one of the areas where badge buddy cards, which are laminated reference sheets that attach to staff ID badges, have been shown in published implementation studies to improve nurse readiness.

Medication safety during downtime

Medication errors are among the most documented harms associated with EHR downtime. When the system is offline, pharmacy, nursing, and prescribing teams may lose access to current medication lists, allergy records, and order histories simultaneously. The drill should therefore test how each group handles this gap.

Specific scenarios to rehearse include:

Verifying an existing medication order without EHR access
Managing a new prescription when clinical decision support is unavailable
Communicating a critical allergy flag from nursing to pharmacy by paper
Handling a controlled substance order when the usual electronic verification cannot be completed

The Institute for Safe Medication Practices recommends assigning a dedicated downtime response team, with designated leaders on call to oversee medication safety during extended outages.

Documentation and order management

All orders, assessments, and clinical notes generated during downtime need to be documented on paper, tracked, and then entered into the EHR system during the recovery phase. The drill should confirm that paper forms are stocked, accessible, and understood by staff in each unit; that there is a defined process for numbering and collecting downtime documents; and that staff know which actions require immediate documentation versus which can be logged during recovery.

A standardized naming convention for patients seen during downtime is important for laboratory and radiology workflows, in particular, where specimens and images may need to be matched to a patient record that was created or updated while the EHR was unavailable.

Internal communications and escalation

When the EHR is offline, the communication infrastructure that coordinates care across departments also degrades. Automated alerts, results notifications, and order confirmations stop flowing. The drill should establish and test an alternative communication protocol: who notifies each clinical area when downtime begins, what the expected update frequency is, and what channel (telephone tree, whiteboard, radio) carries clinical communications during the event.

Escalation criteria should also be established in advance, since not every situation that triggers an EHR alert during normal operations warrants the same response during downtime. The drill should clarify which conditions require immediate escalation to a physician or charge nurse, regardless of system availability.

Recovery and reconciliation

Returning to full EHR functionality is not a passive event. Paper records created during downtime need to be scanned and entered, orders verified and reconciled, and any discrepancies between downtime documentation and the pre-downtime record resolved. The drill should cover who is responsible for each component of this reconciliation, how long it is expected to take, and what the priority order is for entering data generated during the outage.

A safe return to normal operations depends on how well these steps are coordinated. Research examining a major EHR downtime event in Australia highlighted the importance of effective communication during the transition back to electronic records. This recovery phase, sometimes called the uptime procedure, requires as much planning and coordination as the downtime response itself.

Our team helps healthcare practices and facilities develop and update EHR downtime procedures and clinical IT continuity plans, including practical drill programs tailored to their needs. Get in touch to discuss how we can help your organization prepare for EHR outages.

When the EHR goes offline: Building a downtime drill for your clinical team

EHR downtime can disrupt essential clinical workflows, delay access to patient information, and complicate medication management. Without clear procedures and adequate preparation, these disruptions can put patient safety and continuity of care at risk. A written contingency plan is a starting point, but regular drills help staff practice the workflows they need to maintain care when the system goes offline.
Why drills expose what plans miss

When the EHR is unavailable, clinicians face specific, concrete problems: How do you confirm a patient’s identity without a pull-up? Where are the paper order forms? Who decides when to escalate a medication question that normally gets answered by checking the chart? These are procedural muscle-memory questions, and they are only answered reliably by practice rather than by reading a checklist.

The Academic Medical Center Patient Safety Organization’s downtime task force guidelines specifically recommend running drills as part of a complete downtime preparedness program, alongside staff training and a communication triage procedure. The US Department of Health and Human Services’ Administration for Strategic Preparedness and Response (ASPR) also provides a collection of EHR downtime resources to help healthcare organizations prepare for outages and maintain patient safety.

Patient identification: The highest-risk workflow

Analysis of patient safety events during EHR downtime consistently highlights patient identification and clinical information communication as the two areas of greatest risk. When the EHR system is unavailable, clinicians cannot verify patient identity through the standard electronic process, and the manual alternatives need to be established and practiced before they are needed.

The drill should walk through how staff confirm patient identity using two manual identifiers, where paper wristbands are stored and how they are applied, and what process is used to flag patients whose records may have been updated during the outage and need to be reconciled once the system returns. This is one of the areas where badge buddy cards, which are laminated reference sheets that attach to staff ID badges, have been shown in published implementation studies to improve nurse readiness.

Medication safety during downtime

Medication errors are among the most documented harms associated with EHR downtime. When the system is offline, pharmacy, nursing, and prescribing teams may lose access to current medication lists, allergy records, and order histories simultaneously. The drill should therefore test how each group handles this gap.

Specific scenarios to rehearse include:

Verifying an existing medication order without EHR access
Managing a new prescription when clinical decision support is unavailable
Communicating a critical allergy flag from nursing to pharmacy by paper
Handling a controlled substance order when the usual electronic verification cannot be completed

The Institute for Safe Medication Practices recommends assigning a dedicated downtime response team, with designated leaders on call to oversee medication safety during extended outages.

Documentation and order management

All orders, assessments, and clinical notes generated during downtime need to be documented on paper, tracked, and then entered into the EHR system during the recovery phase. The drill should confirm that paper forms are stocked, accessible, and understood by staff in each unit; that there is a defined process for numbering and collecting downtime documents; and that staff know which actions require immediate documentation versus which can be logged during recovery.

A standardized naming convention for patients seen during downtime is important for laboratory and radiology workflows, in particular, where specimens and images may need to be matched to a patient record that was created or updated while the EHR was unavailable.

Internal communications and escalation

When the EHR is offline, the communication infrastructure that coordinates care across departments also degrades. Automated alerts, results notifications, and order confirmations stop flowing. The drill should establish and test an alternative communication protocol: who notifies each clinical area when downtime begins, what the expected update frequency is, and what channel (telephone tree, whiteboard, radio) carries clinical communications during the event.

Escalation criteria should also be established in advance, since not every situation that triggers an EHR alert during normal operations warrants the same response during downtime. The drill should clarify which conditions require immediate escalation to a physician or charge nurse, regardless of system availability.

Recovery and reconciliation

Returning to full EHR functionality is not a passive event. Paper records created during downtime need to be scanned and entered, orders verified and reconciled, and any discrepancies between downtime documentation and the pre-downtime record resolved. The drill should cover who is responsible for each component of this reconciliation, how long it is expected to take, and what the priority order is for entering data generated during the outage.

A safe return to normal operations depends on how well these steps are coordinated. Research examining a major EHR downtime event in Australia highlighted the importance of effective communication during the transition back to electronic records. This recovery phase, sometimes called the uptime procedure, requires as much planning and coordination as the downtime response itself.

Our team helps healthcare practices and facilities develop and update EHR downtime procedures and clinical IT continuity plans, including practical drill programs tailored to their needs. Get in touch to discuss how we can help your organization prepare for EHR outages.

Browser extensions are software too: A security checklist for business PCs

Browser extensions are treated as convenient add-ons rather than what they actually are: software installed on a business computer with significant access to network traffic, browsing data, and, in some cases, stored credentials. The Cybersecurity and Infrastructure Security Agency (CISA) has explicitly noted that browser extensions can carry high privilege levels and introduce substantial security concerns. For businesses that haven’t reviewed their extension landscape recently, this checklist covers the areas that are often overlooked.

Understand what permissions extensions actually request

When a browser extension is installed, it requests a set of permissions that define what it can access. Many users click through these prompts without reading them, but the permissions matter significantly. An extension with access to all data on all websites can observe every page a user visits, read form inputs, capture credentials, and intercept communications between the browser and web services. This level of access is not unusual for legitimate tools such as ad blockers and password managers, but it is also the level of access a malicious extension needs to do serious damage.

As part of any audit, open the browser’s extension management page and review the stated permissions for each installed extension. Extensions that request broader permissions than their stated function requires warrant closer scrutiny. A PDF viewer that requests access to read and change all data on all websites, for example, is asking for significantly more access than PDF viewers should need.

Identify extensions that are abandoned or no longer maintained

Software that is no longer actively maintained does not receive security updates. An extension that was secure when installed may develop unpatched vulnerabilities over time if its developer stops updating it. Worse, CISA and security researchers have documented cases where abandoned extensions are sold to new owners who convert them into adware or spyware, taking advantage of the existing install base and previously granted permissions.

Check the last update date for each extension installed on business devices. Extensions that have not been updated in a year or more, particularly those from developers who appear to have stopped maintaining them, should be evaluated for removal. You can usually find the last-updated date on the browser’s extension page or in the extension’s web store listing.

Watch for extensions with legitimate covers and hidden behavior

Not all problematic extensions are obviously malicious. Some legitimate ad blockers have been known to accept payments from advertisers to ensure those advertisers’ content bypasses the blocker, undermining the tool’s purpose. Others collect browsing data for commercial purposes that are disclosed deep in a terms-of-service document rather than clearly communicated during installation.

When evaluating extensions for business use, give preference to tools with a clear commercial model and a reputable developer, where the business relationship between developer and user is transparent. Free extensions with large install bases and no obvious revenue model are worth extra scrutiny: the data access they hold may itself be the product.

Build an allowlist and remove everything outside it

The most effective organizational control over browser extensions is an allowlist: a defined set of approved extensions that employees may install, managed through browser enterprise policy. Extensions outside the allowlist are blocked from installation. This approach is supported by Chrome, Edge, and Firefox through their respective enterprise management frameworks, and it is the control CISA recommends as the foundation of browser security management.

Building the allowlist requires reviewing which extensions current employees use, evaluating each for business justification and permission scope, and removing those that don’t meet the criteria. The process takes time but eliminates the need to reactively investigate individual extension incidents after the fact.

Schedule regular audits and enforce removal procedures

Browser extensions accumulate over time, particularly on devices where employees have administrator rights. A quarterly review of installed extensions across managed devices catches new installations that haven’t gone through the approval process, identifies newly abandoned extensions, and provides an opportunity to remove tools that are no longer actively used.

The removal process for extensions that don’t meet the allowlist standard should be documented and consistently applied. Extensions that hold sensitive permissions should be removed promptly rather than left in place pending review. Once an extension has collected data, removing it cannot undo that collection, so speed matters when a problematic tool is identified.

Managing browser extension risks across your organization requires the right policies and controls. Our team can help you assess your current exposure and implement security measures that fit your environment. Get in touch to get started.